All projects

Manufacturing RAG Assistant

Independent open-source retrieval-augmented generation demo

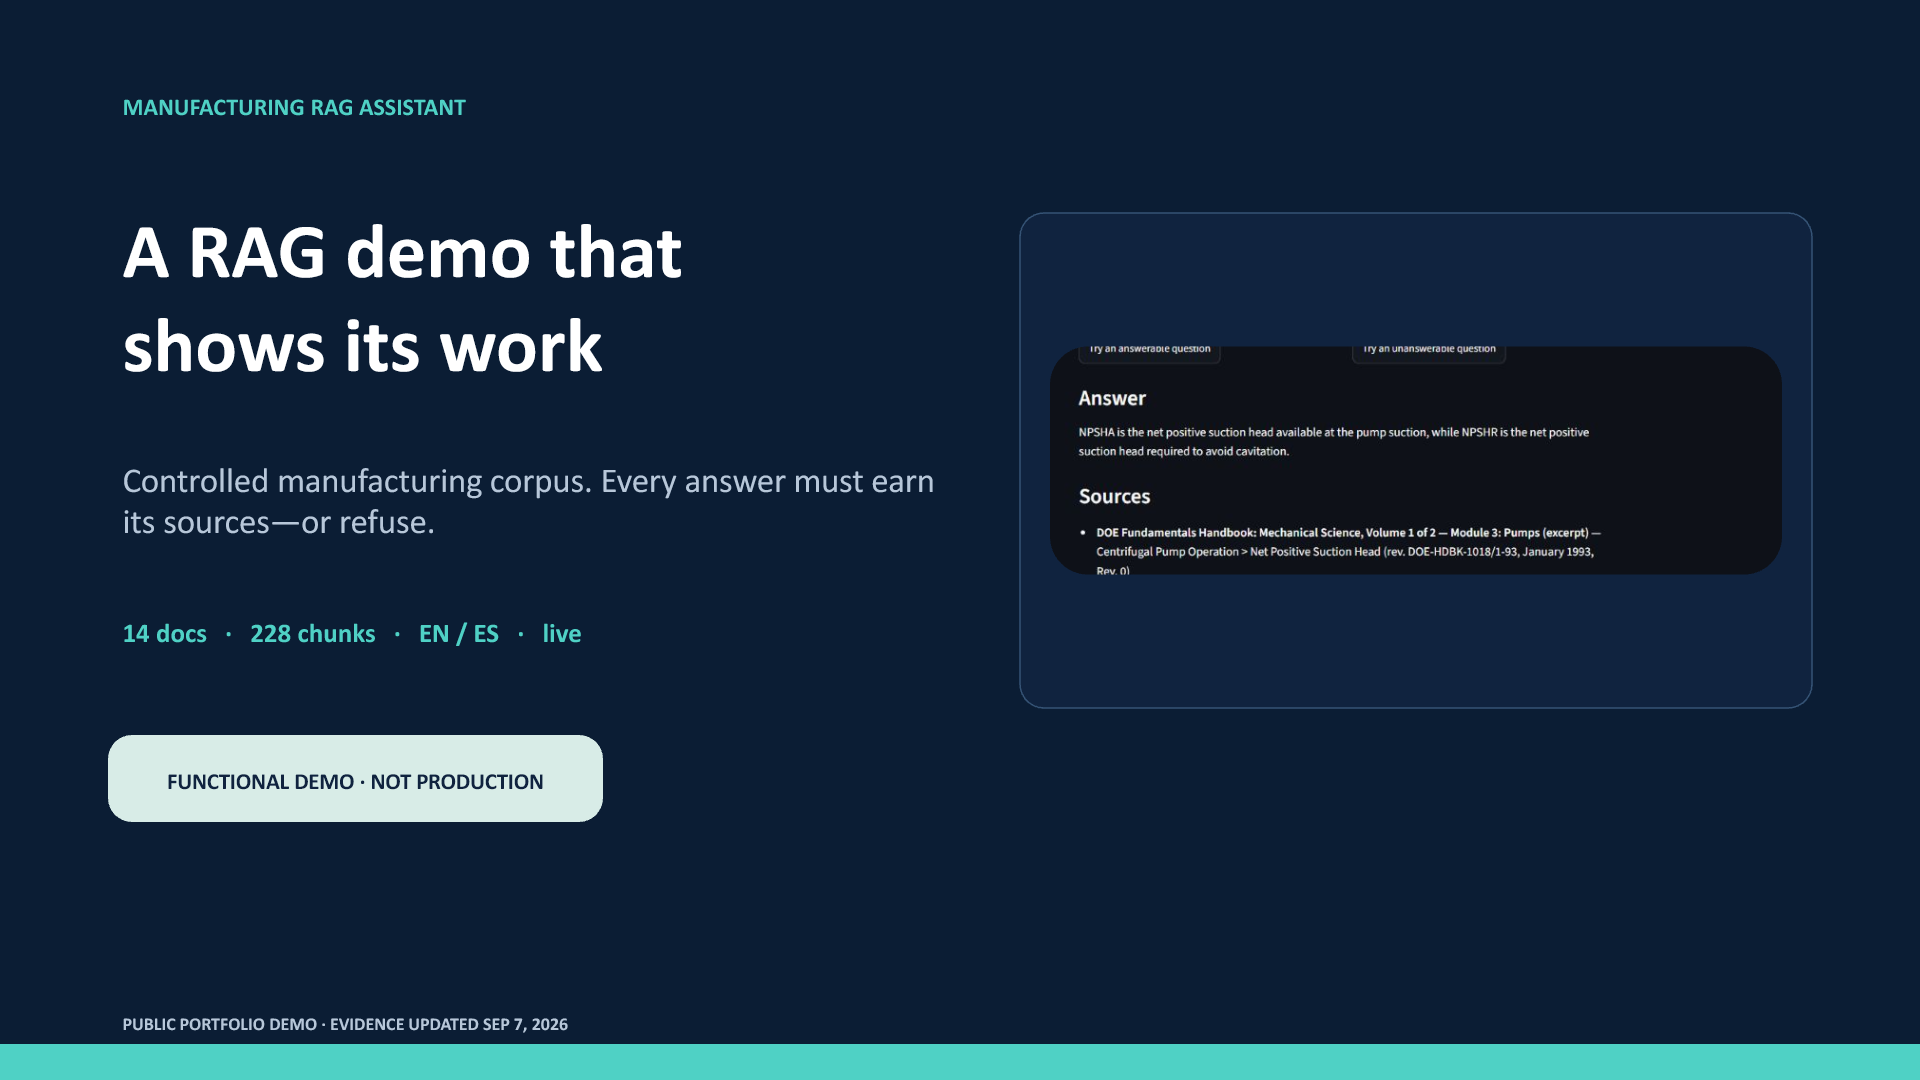
A bilingual public demo that retrieves from a controlled manufacturing corpus, cites its sources, and refuses when evidence is insufficient.

Status
Published
Evidence
Sep 7, 2026
Stack
Python · FastAPI · BM25 · BAAI/bge-m3 · Docker · Hugging Face Spaces

Evidence updated Sep 7, 2026 · source 60420f1 (opens in a new tab)

02

Executive summary

General assistants can answer fluently without exposing whether the answer is supported by the documents that matter.

This demo tests a narrower behavior: retrieve evidence from a declared manufacturing corpus, answer with citations, or refuse.

My scope

Designed and built the controlled corpus, hybrid retrieval, evidence threshold, cited bilingual answer flow, protected container boundary, evaluation suite, and reproducible deployment pipeline.

03

What I built

  1. 01

    Index nine public and five clearly labeled synthetic documents into 228 inspectable chunks.

  2. 02

    Combine BM25 lexical retrieval with BAAI/bge-m3 semantic retrieval before applying an evidence threshold.

  3. 03

    Require cited output and turn weak or uncited results into an explicit refusal.

  4. 04

    Expose only the UI, health, and readiness routes through nginx while keeping the query API internal.

04

Architecture and data flow

The flow keeps corpus provenance, retrieval, refusal, generation, citations, and the public boundary inspectable.

  1. 01

    Controlled corpus

    Nine public and five labeled synthetic manufacturing documents.

  2. 02

    Hybrid retrieval

    BM25 and BAAI/bge-m3 retrieve lexical and semantic evidence.

  3. 03

    Refusal gate

    A documented threshold blocks evidence that is too weak.

  4. 04

    Answer with sources

    The external LLM generates only after retrieval passes; uncited output is rejected.

05

Evaluation and live verification

  • On the profile actually served (contextual-v1 with expansion off), the frozen retrieval evaluation reports Recall@5 of 0.887 overall: 0.917 in English (n=48) and 0.844 in Spanish (n=32).
  • Recall@3 is 0.825 and mean reciprocal rank is 0.721 on that same retrieval profile and eval_set v1.1.0.
  • Generation metrics remain historical raw-v1 / eval_set v1.0.0 measurements: correct refusal 0.900, false refusal 0.200, human-reviewed faithfulness 29/30 (0.967), and citation accuracy 23/30 (0.767). They were not re-measured on contextual-v1.
  • On Sep 7, 2026, the public deployment, bilingual UI, privacy notice, and linked evidence were re-verified; the answer capture shown in the deck remains dated Aug 29.

06

Measured evidence

Retrieval, refusal, faithfulness, and citation quality remain distinct signals.

14

corpus documents

Represents
Nine public and five synthetic documents with explicit provenance.
Why it matters
The answerable scope is visible and reproducible.
Does not show
It is not broad industrial knowledge coverage.

228

indexed chunks

Represents
The searchable units built from the controlled corpus.
Why it matters
Retrieval operates over a bounded, inspectable index.
Does not show
It is not a scale or latency benchmark.

0.887

Recall@5

Represents
Retrieval coverage at five results on eval_set v1.1.0 and the served contextual-v1/off profile.
Why it matters
Retrieval quality is measured independently from answer fluency.
Does not show
It does not guarantee every answer is correct.

0.900

historical correct refusal

Represents
The raw-v1 / eval_set v1.0.0 generation run's rate for refusing unsupported questions.
Why it matters
Abstention was evaluated as product behavior.
Does not show
It was not re-measured on contextual-v1; historical false refusal was 0.200.

0.967

historical faithfulness

Represents
Twenty-nine of thirty human-reviewed raw-v1 answers stayed supported by retrieved evidence.
Why it matters
Grounding was evaluated separately from retrieval.
Does not show
It was not re-measured on contextual-v1; historical citation accuracy was 0.767 and missed its target.

07

Honest limits

  • This is a functional public portfolio demo, not a production or industrial system.
  • It represents no factory, client deployment, business result, savings, or error elimination.
  • Coverage is limited to the controlled corpus; unsupported questions should be refused.
  • Questions and retrieved context are sent to the configured external LLM provider; confidential or regulated input should not be entered.
  • Hugging Face may cold-start the Space, and live availability can change after the evidence date.
  • Generation metrics are historical raw-v1 measurements, were not re-measured on contextual-v1, and historical citation accuracy remained below target.
  • Spanish questions depend strongly on cross-lingual semantic retrieval because BM25 has little lexical overlap with the English-only corpus; the contextual profile improves measured retrieval but does not remove that design constraint.

08

Source and provenance

Claims are bounded by the pinned repository commit, documented evaluations, and a dated live check.

View full provenance
Evidence date
2026-09-07
Documents consulted
  • README.md
  • SPEC.md
  • corpus/SOURCES.md
  • eval/reports/retrieval_report_v1.1.0__contextual-v1__off.md
  • eval/reports/generation_eval_v1.0.0.md
  • eval/reports/threshold_analysis_v1.0.0.md
  • nginx.conf
  • .github/workflows/deploy-hf-space.yml
Licensing
Project code and documentation are published under the repository's MIT license; source documents retain their original terms.